
Site Reliability Engineer (SRE)
Configuration-as-Code - Terraform Deployment for AI Workloads
The Business Problem
A new Private AI workload requires a load balancer configuration with specific requirements: session persistence for stateful inference endpoints, extended timeouts for long-running model calls, connection multiplexing, and gradual traffic ramp for rolling deployment. Writing Terraform for this requires deep knowledge of the AVI Terraform provider resource schema, correct attribute names for the target provider version, and validation across multiple environments before production rollout.
Typical timeline: 2-3 days from requirements to validated, state-tracked Terraform configuration.
How Zenera Solves It
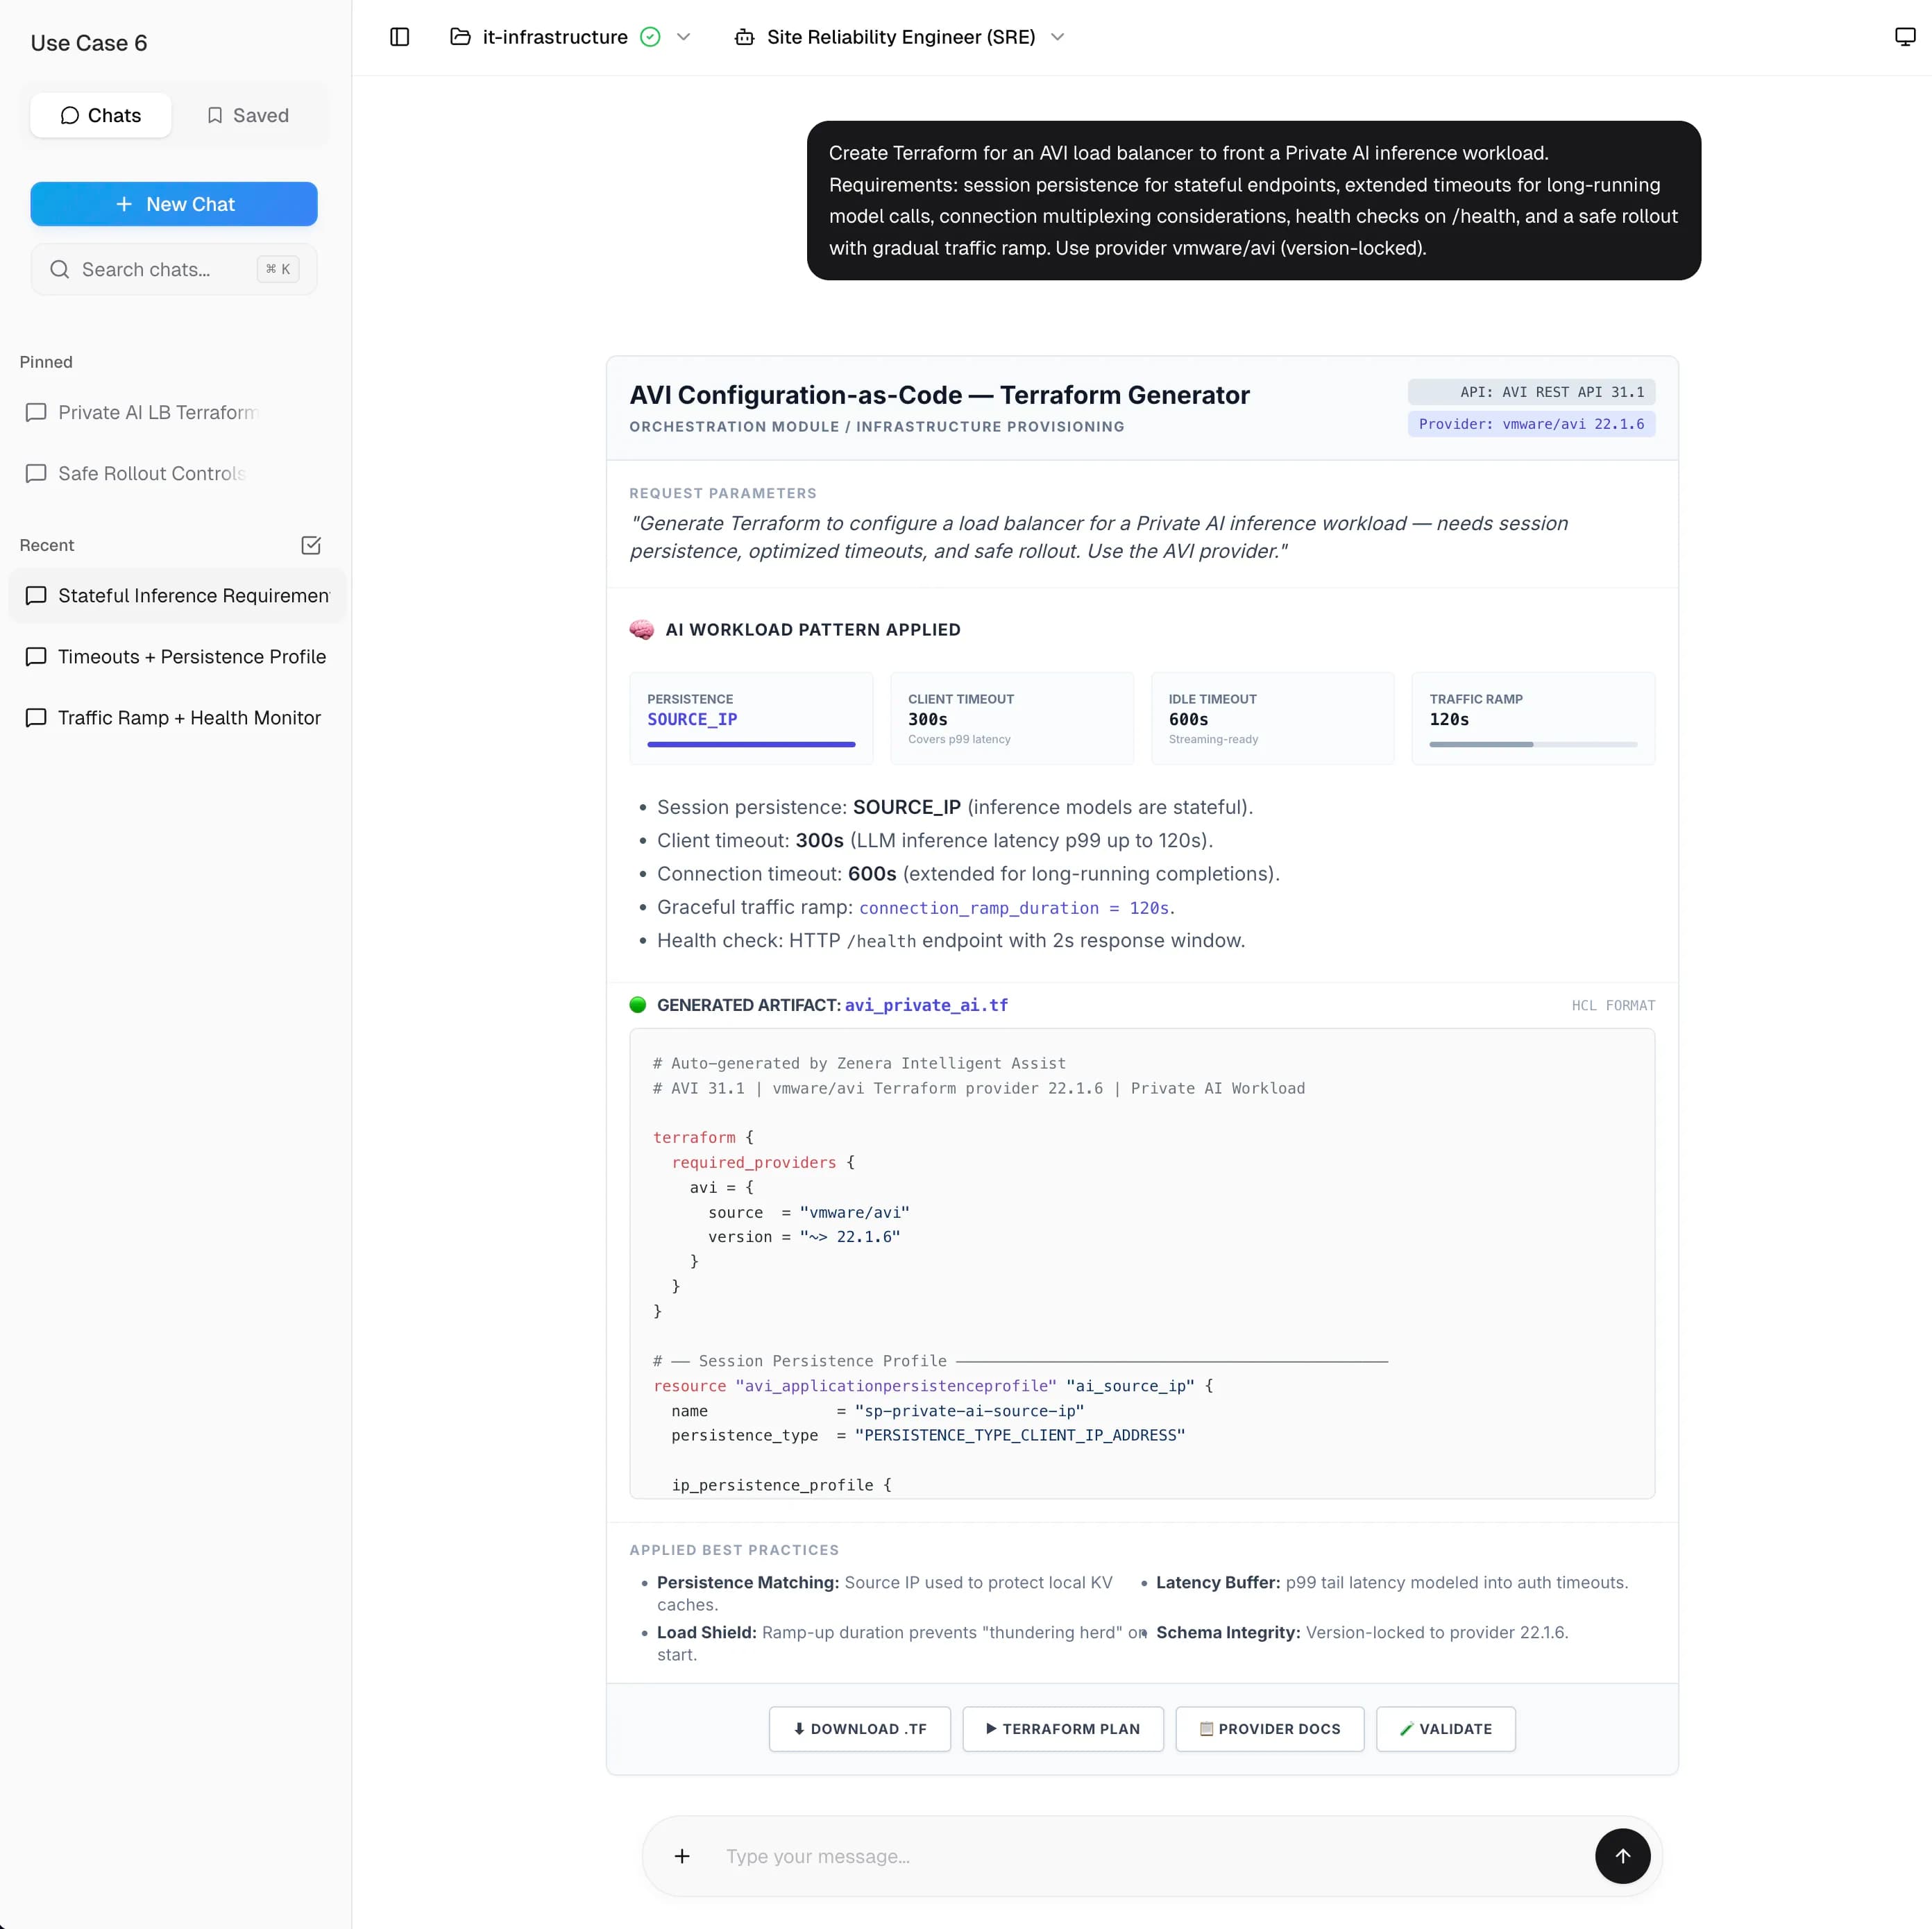
Intelligent Assist execution:
- 1Workload pattern recognition: Understood "Private AI workload" requirements and applied AI-inference-specific best practices - source IP persistence for stateful models, extended client_auth_timeout and connection_idle_timeout for long-running inference calls
- 2Provider schema comprehension: Mapped workload requirements to the correct vmware/avi Terraform provider resource types and attribute names, scoped to provider version 22.1.6 to avoid deprecated fields
- 3Best-practice application: Generated connection_ramp_duration to prevent thundering-herd on pool activation, added a dedicated health monitor with a tight receive_timeout for fast failure detection, and split credentials into sensitive variables
- 4State-ready output: Produced idiomatic Terraform with correct resource dependency ordering (avi_pool references avi_healthmonitor and avi_applicationpersistenceprofile), enabling clean terraform plan / terraform apply without manual edits
Time to production-ready Terraform
3 minutes (vs. 2-3 days manual development and validation)